The memory wall
A model needs to move data from memory to produce an answer. The speed of that data transfer can limit how fast it writes.
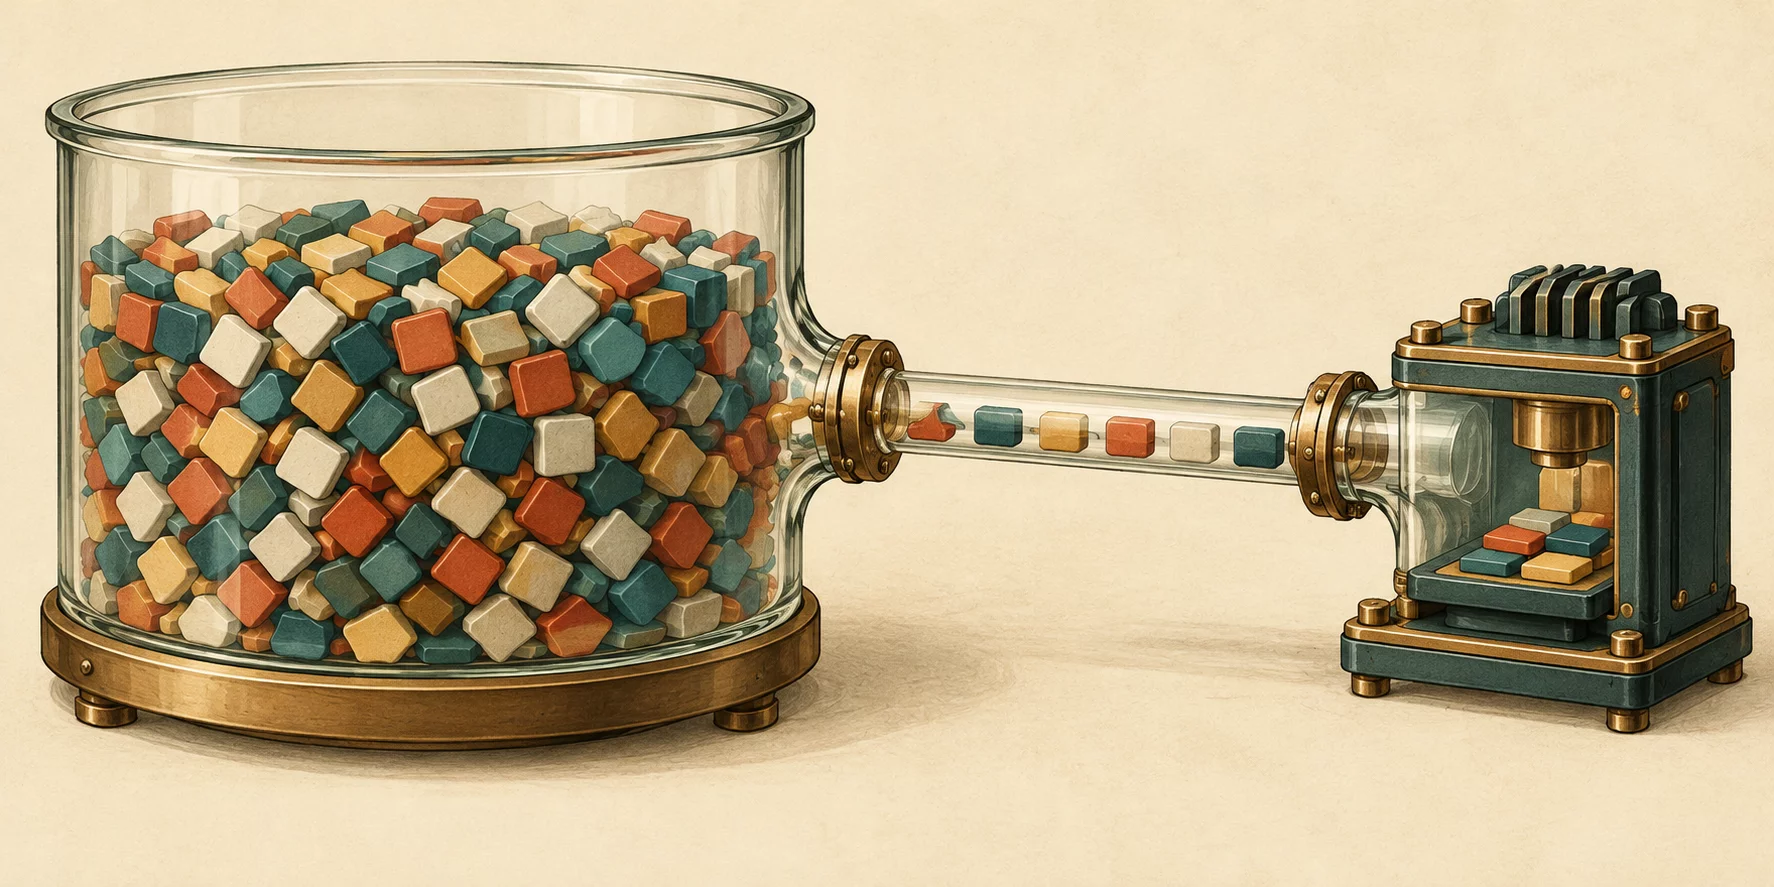
Memory bandwidth is how much data a device can move each second. When that transfer is the bottleneck, moving less data can make a reply faster.
The arithmetic
Show the labeled diagram
Scroll sideways to see the full diagram.
A dense model uses most of its learned numbers, called weights, for each new token. As a rough estimate, multiply the number of active weights by the space each weight takes. A 4-bit weight uses about half a byte, plus some extra storage. An 8-bit weight uses about one byte.
For one request, this rough model assumes the active weights and the full cache for its current context are read once per step. Cache capacity per stored token is not the traffic for one generated token. Actual traffic can differ because of caching, attention layout, and kernels. At larger batches, weight reads can be shared across requests.
The ceiling is the achieved memory bandwidth divided by those bytes:
For a 27B dense model at 8 bits, the weights are about 27 GB before overhead. Ignoring cache traffic, 273 GB/s gives an optimistic weight-only estimate of about 10 tokens per second.
A sparse mixture-of-experts model reads only its active experts. A model with 3B active parameters at 4 bits reads about 1.5 GB per token. The same bandwidth gives a ceiling near 180 tokens per second. Real kernels, caches, and routing overhead reduce the achievable rate.
The ceiling is not a promise. It is the best case if every byte of bandwidth moved useful data. Real decode reaches part of it. Achieved bandwidth depends on the workload and implementation. Sparse models and long context often do worse, because routing and cache reads add overhead.
When memory is the limit
A roofline model helps compare two possible limits: how quickly a device can calculate, and how quickly it can move data. It uses arithmetic intensity, the number of operations performed for each byte moved. Work with low intensity can be limited by memory speed; work with high intensity may be limited by calculation speed. The dividing point is peak calculation speed divided by peak memory bandwidth.
In a simple batch-one matrix-vector estimate, each weight contributes about two operations. At 4 bits per weight, that is about 4 operations per byte before overhead. For an illustrative device with 100 trillion operations/s and 1 trillion bytes/s, the dividing point is 100 operations per byte. A workload doing only 4 operations per byte is limited by data movement in this model. Larger batches and different kernels can change the balance.
Prefill is different. Many prompt tokens share one weight read, so the intensity rises. A long prompt can become compute-bound. That is why prefill and decode need different kernels and different tuning.
What changes the ceiling
| Lever | Effect on bytes per token | Cost or limit |
|---|---|---|
| Lower precision | Weight payload falls with bits; overhead varies | Quality loss, kernel support, scale overhead |
| Fewer active parameters | Falls with the active count | Model capacity, routing quality |
| Larger batch | Weights are shared, so bytes per request fall | Cache memory, latency, queueing |
| Speculative decoding | More accepted tokens per weight read | Draft cost, acceptance rate |
| Shorter context | Less KV cache traffic | Less history or fewer documents |
Batching helps because one weight read serves many requests. The aggregate rate can rise, but each request waits longer for its next token. At large batches, the cache traffic dominates, and the aggregate rate levels off.
Speculative decoding helps for a different reason. A draft model proposes several tokens. The main model checks them in one pass. If the draft is accepted, one weight read produced several tokens. That raises the effective tokens per byte. The gain depends on the acceptance rate, which is covered on the MTP page.
Hardware limits
Memory bandwidth is a hardware property. The GB10 machine has a specified memory bandwidth of 273 GB/s. A workload can achieve less than the specification. Data-center accelerators have much more, often several TB/s. Apple silicon uses unified memory with a different balance of capacity and bandwidth. The ceiling formula is the same on every device.
Capacity is a separate limit. If the weights and cache do not fit, they cannot all stay on that device. Offloading or splitting the model across devices adds transfer costs. A 27B model at 4 bits needs about 12.6 GiB for weights. The same model at 8 bits needs about 25 GiB. Add the cache, activations, and the runtime, then leave headroom for the operating system.
How to use the number
Start with the ceiling. If a model needs 100 tokens per second and the ceiling is 40, no kernel tuning will close the gap. Change the precision, the active parameter count, or the hardware.
Then measure achieved bandwidth. If the achieved rate is far below the ceiling, profile the kernels and check the cache traffic. If it is close, the remaining gains are small.
Keep the units clear. A parameter is a number. A byte is eight bits. A model with 27B parameters at 4 bits has about 13.5 GB of weights, not 27 GB. Scale overhead and alignment add a little.